
Artificial Intelligence
Building intelligent machines that complement human reasoning and extend what people can do.
Project
Foundation Models
Larges-scale Pre-training across Tasks, Languages and Modalities Large-scale Self-supervised Pre-training across Tasks, Languages, and Modalities (opens in new tab).
Video
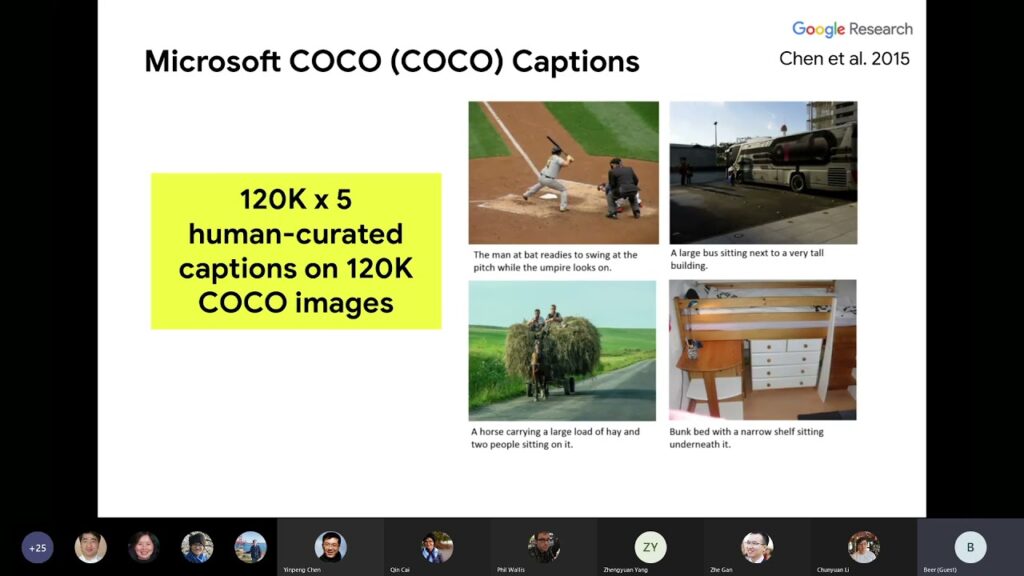
Tightly Connecting Vision and Language
Remarkable progress has been made at the intersection of vision and language. While showing great promise, current vision and language models may only weakly “connect” the two modalities and often fail in the wild. In…
Tool
ORBIT Dataset
The ORBIT dataset is a collection of videos of objects in clean and cluttered scenes recorded by people who are blind/low-vision on a mobile phone. The dataset is presented with a teachable object recognition benchmark…
Project
Watch For
Transitioned | Watch For is a large-scale, low-cost, highly programmable media analysis platform built on Azure.