
Human language technologies
Advancing how machines understand and generate human language across speech, text, and translation.
Microsoft Research 블로그
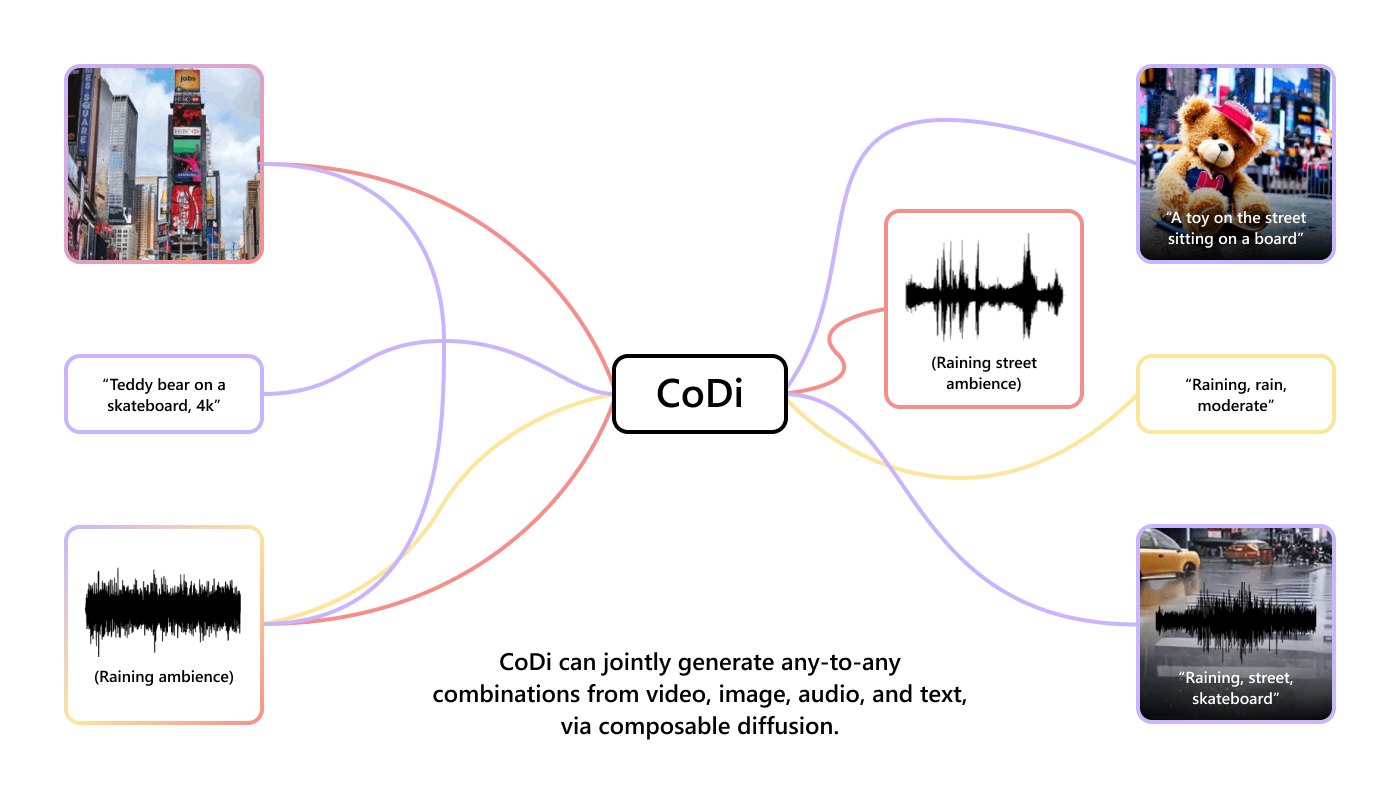
Breaking cross-modal boundaries in multimodal AI: Introducing CoDi, composable diffusion for any-to-any generation
Imagine an AI model that can seamlessly generate high-quality content across text, images, video, and audio, all at once. Such a model would more accurately capture the multimodal nature of the world and human comprehension,…
프로젝트
Project VeLLM
uniVersal Empowerment with LLMs Note: This research project has reached its conclusion. These pages are maintained for reference and archival purposes. The technology landscape is being rapidly transformed by Large Language Models (LLMs), allowing users…