Human language technologies
Advancing how machines understand and generate human language across speech, text, and translation.
툴
Microsoft Speech Corpus (Indian languages)
Microsoft Speech Corpus (Indian languages) release contains conversational and phrasal speech training and test data for Telugu, Tamil and Gujarati languages. The data package includes audio and corresponding transcripts. Data provided in this dataset shall…
Microsoft Research 블로그
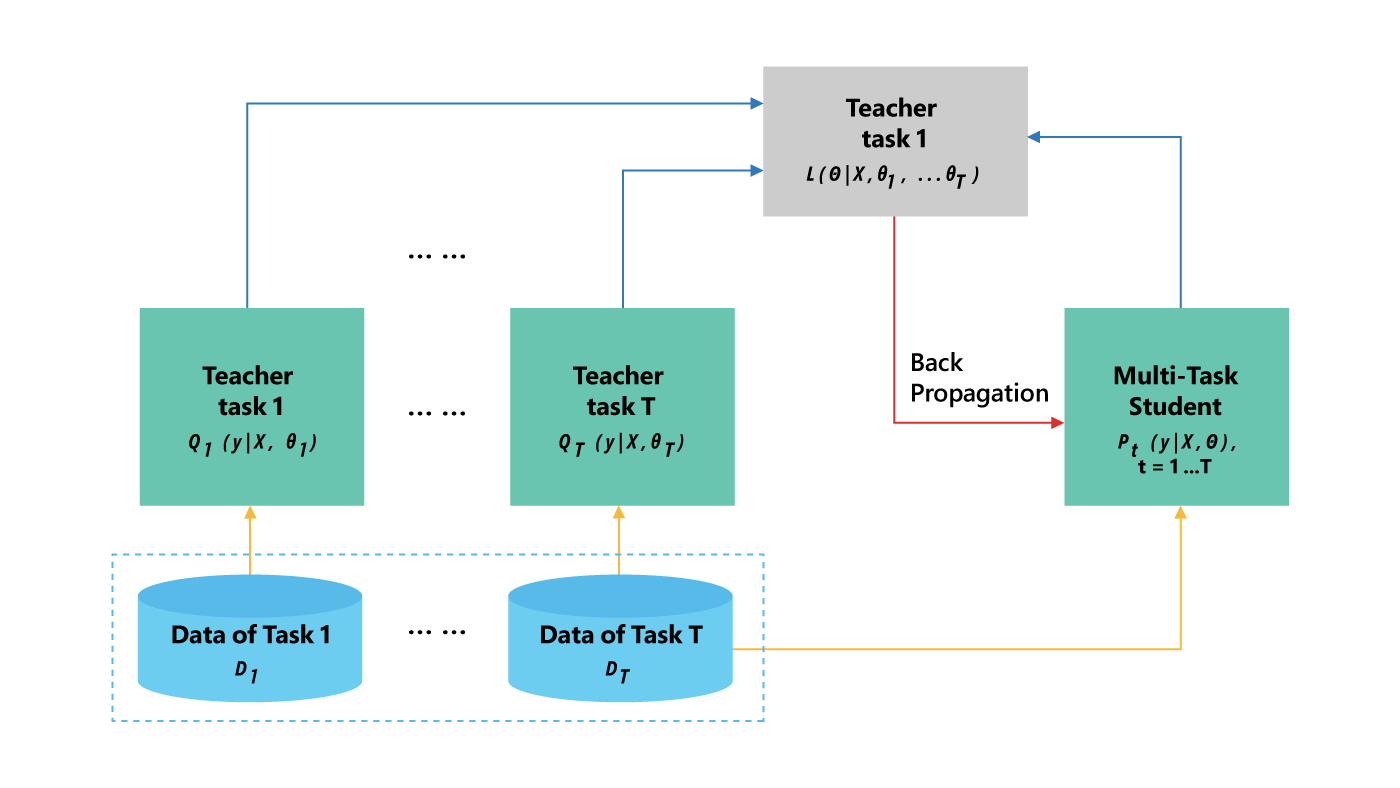
Robust Language Representation Learning via Multi-task Knowledge Distillation
Language Representation Learning maps symbolic natural language texts (for example, words, phrases and sentences) to semantic vectors. Robust and universal language representations are crucial to achieving state-of-the-art results on many Natural Language Processing (NLP) tasks.…