
Artificial Intelligence
Building intelligent machines that complement human reasoning and extend what people can do.
Outil
LiST (Lite Self-Training)
We present a new method LiST for efficient fine-tuning of large pre-trained language models (PLMs) in few-shot learning settings. LiST significantly improves over recent methods that adopt prompt fine-tuning using two key techniques. The first…
Outil
LITMUS Predictor
LITMUS Predictor provides support for simulating performance in ~100 languages given training observations of the desired task-model. Each training observation specifies the finetuning-datasize + test-performance in different languages. Further, the tool provides support for constructing…
Vidéo
Microsoft Research 2021 Global PhD Fellowship Recipients
Meet some of 2021 global PhD Fellowship recipients from around the world.
Outil
DistIR
DistIR is an intermediate representation (IR) and associated set of tools for optimizing distributed machine learning computations (both training and inference). An IR is a format for representing programs used by compilers and software analysis…
Blog de recherche Microsoft
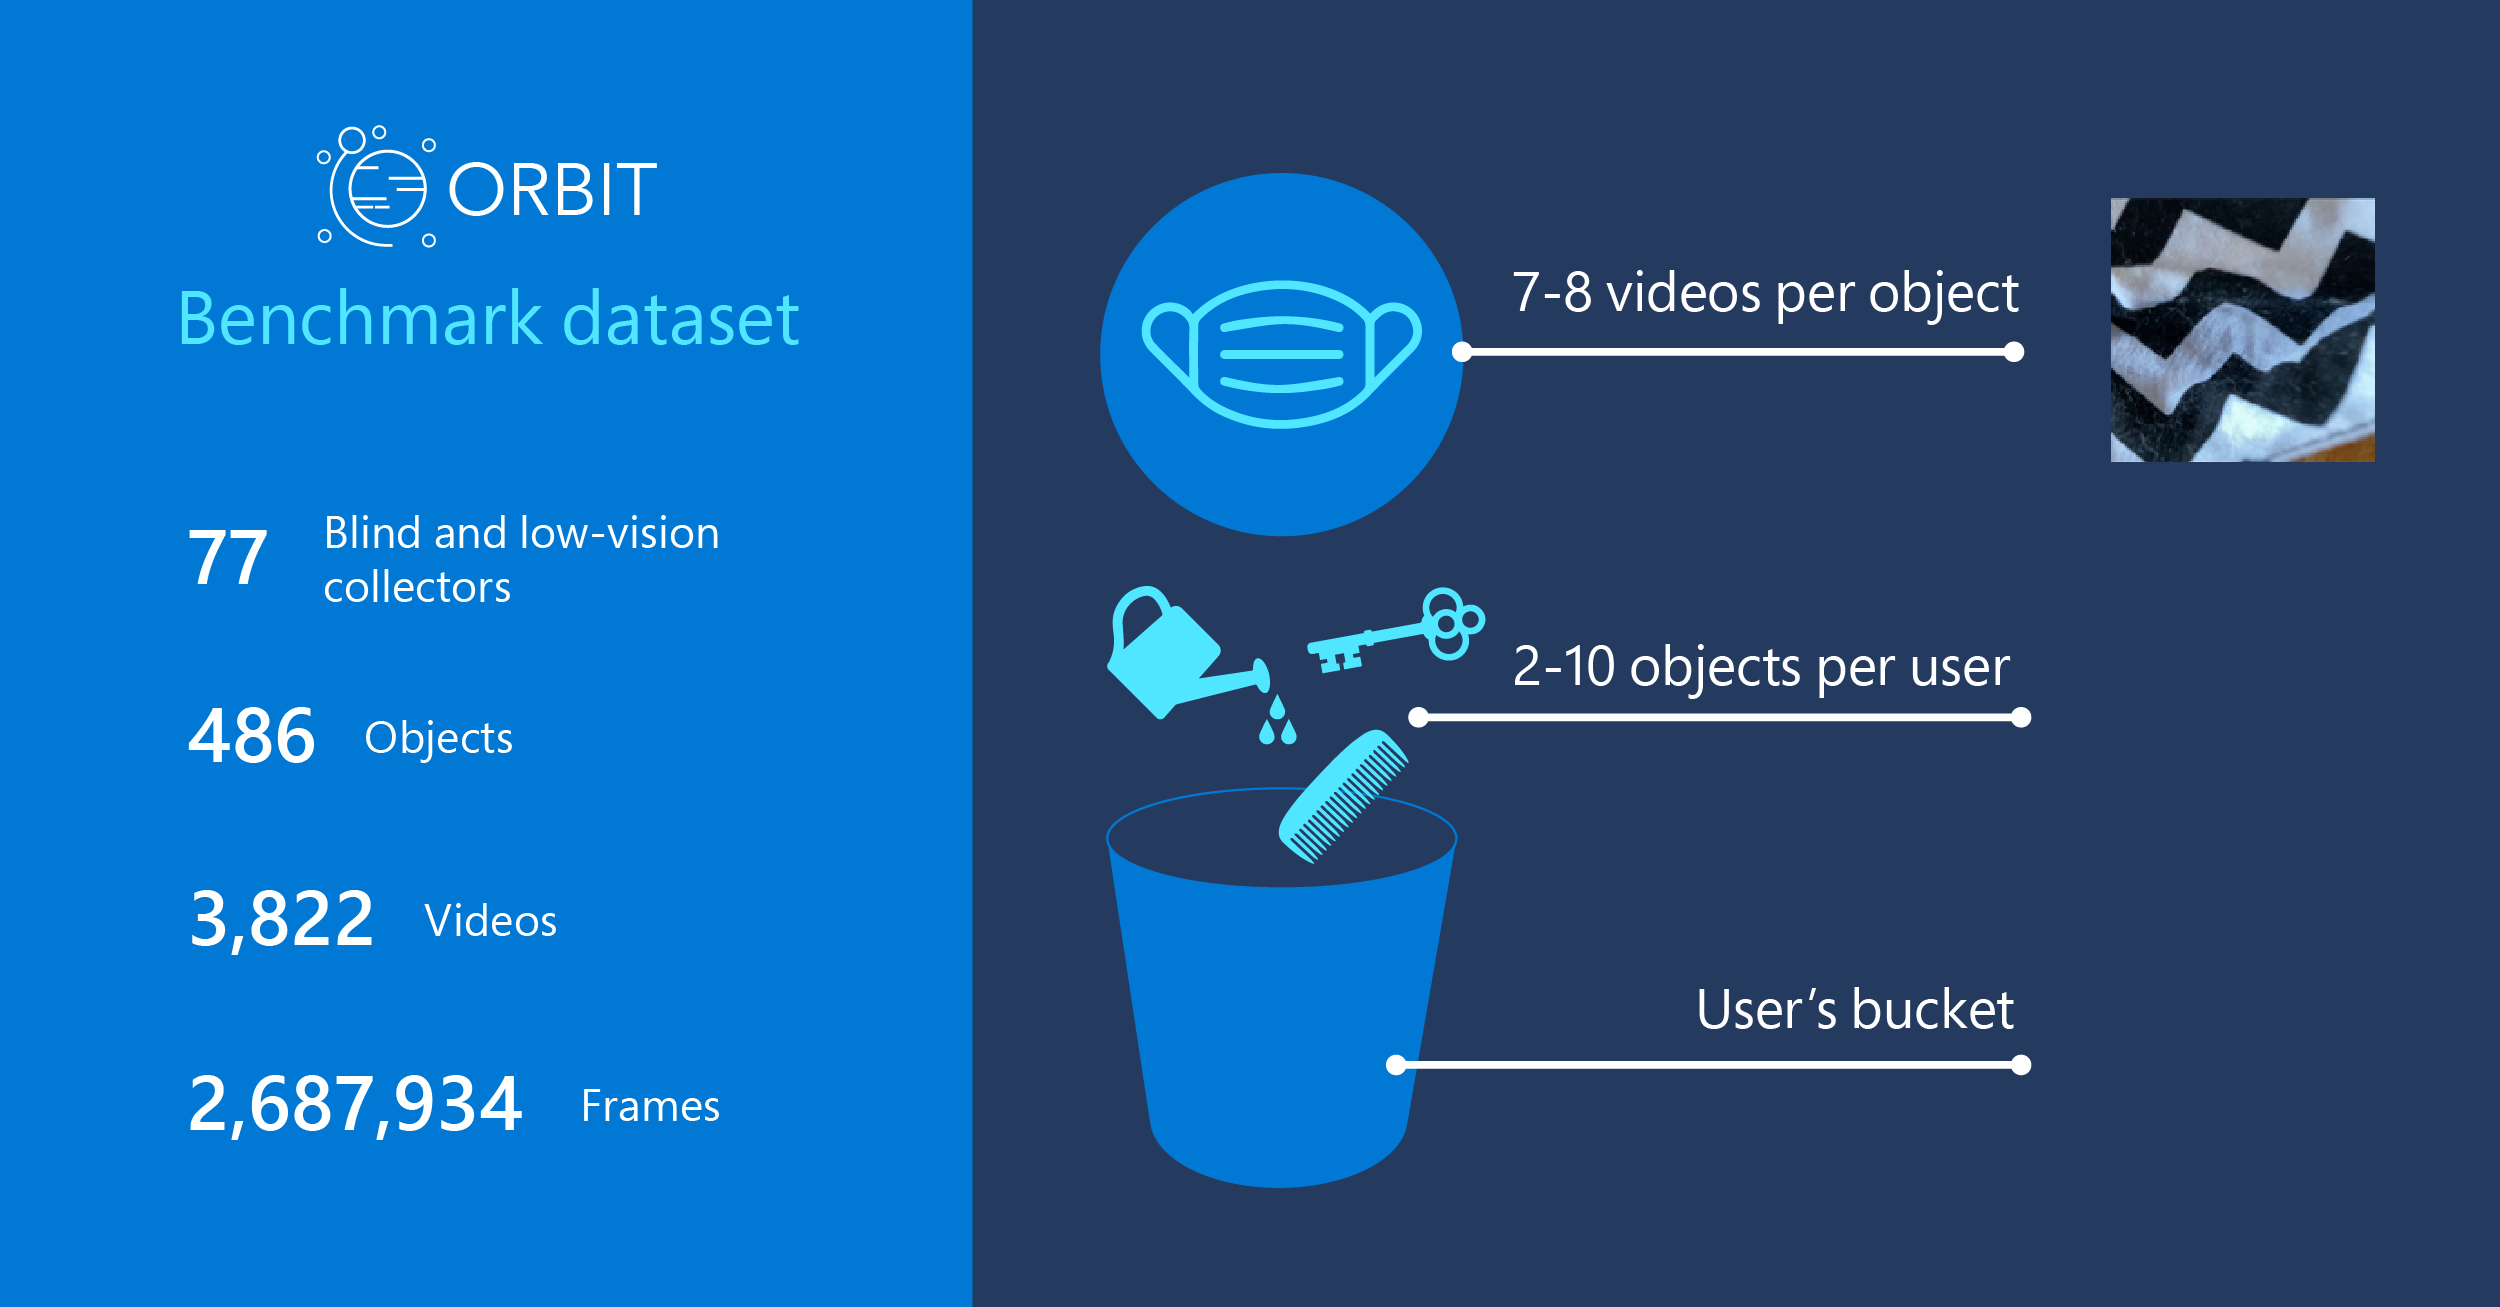
Announcing the ORBIT dataset: Advancing real-world few-shot learning using teachable object recognition
Object recognition systems have made spectacular advances in recent years, but they rely on training datasets with thousands of high-quality, labelled examples per object category. Learning new objects from only a few examples could open…
Projet
Project Maia
By understanding human decisions at a granular level, Maia can help identify a player’s strengths and weaknesses, with the goal of helping them learn and improve their gameplay.